Evaluator models
The model that reads a response and applies a template's criteria to score it
What an evaluator model does
An evaluator model reads a response and applies an eval template’s criteria to produce a result, and an optional reason. It receives the text to evaluate, the template’s rule, and the required inputs, then returns a verdict. An evaluator model only reads and scores; it never generates or edits your AI’s output. Agent Evaluator and LLM-as-Judge evals use an evaluator model; Code Evals do not.
%%{init: {"flowchart": {"curve": "linear"}}}%%
flowchart LR
  IN["Response + template criteria"] --> J["Evaluator model<br/>reads and scores"]
  J --> OUT["Result + optional reason"]
Future AGI evaluator models
Future AGI ships proprietary models built for evaluation, not for general-purpose chat:
| Model | Code | Inputs | Best for | Latency |
|---|---|---|---|---|
| Turing Large | turing_large | Text, image, audio | Max accuracy, multimodal evals | Higher |
| Turing Small | turing_small | Text, image | High fidelity at lower cost | Medium |
| Turing Flash | turing_flash | Text, image | Fast, high-accuracy evals | Low |
| Protect | protect | Text, audio | Safety, guardrails, custom rules | Low |
| Protect Flash | protect_flash | Text | First-pass binary filtering | Ultra-low |
Jev (TypeSafe System One)
Jev is TypeSafe’s System One evaluator. It returns typed decisions with probabilities, not written reasoning. It is available in every edition, including open source, using your organization’s own TypeSafe key. It is not one of Future AGI’s keyless Turing models.
On Cloud, each completed Jev evaluation also uses Future AGI’s flat per-evaluation fee in credits. TypeSafe bills its inference separately to your TypeSafe account.
| Model | Behavior |
|---|---|
jev-1.14.0 | Pins the evaluation to this Jev release |
jev-1.13.0 | Pins the evaluation to this Jev release |
jev-latest | Tracks TypeSafe’s current Jev release |
Use Jev when you want a binary decision, one scored choice or an ordered rubric. Pin a release when a repeatable model version matters; the latest alias can change upstream.
Set up a Jev evaluator
Add your TypeSafe key
Open Settings > AI Providers and add the organization’s TypeSafe key. If no key is saved, the evaluator model selector offers a way to add it. Future AGI does not substitute an operator key.
Choose the model and instructions
Create or edit an evaluator in Evals, then select Jev 1.14, Jev 1.13 or Jev latest under Decision models in the model picker. Write the decision rule and map its template variables to the data to evaluate.
Jev reads the mapped text. It does not run tools, browse the internet or retrieve knowledge-base content for you.
Inputs have a size limit, separate from the gateway’s request limit: by default 256 KiB for the serialized request and about 30,000 tokens of mapped text (estimated as characters divided by four). A larger input is refused with JEV_INPUT_TOO_LARGE. Map a smaller field, such as a session’s transcript instead of its raw spans; embedded images make inputs large quickly.
Configure the output
Choose one of the supported output types below. Test it on an example before saving and attaching it to a dataset or Observe project.
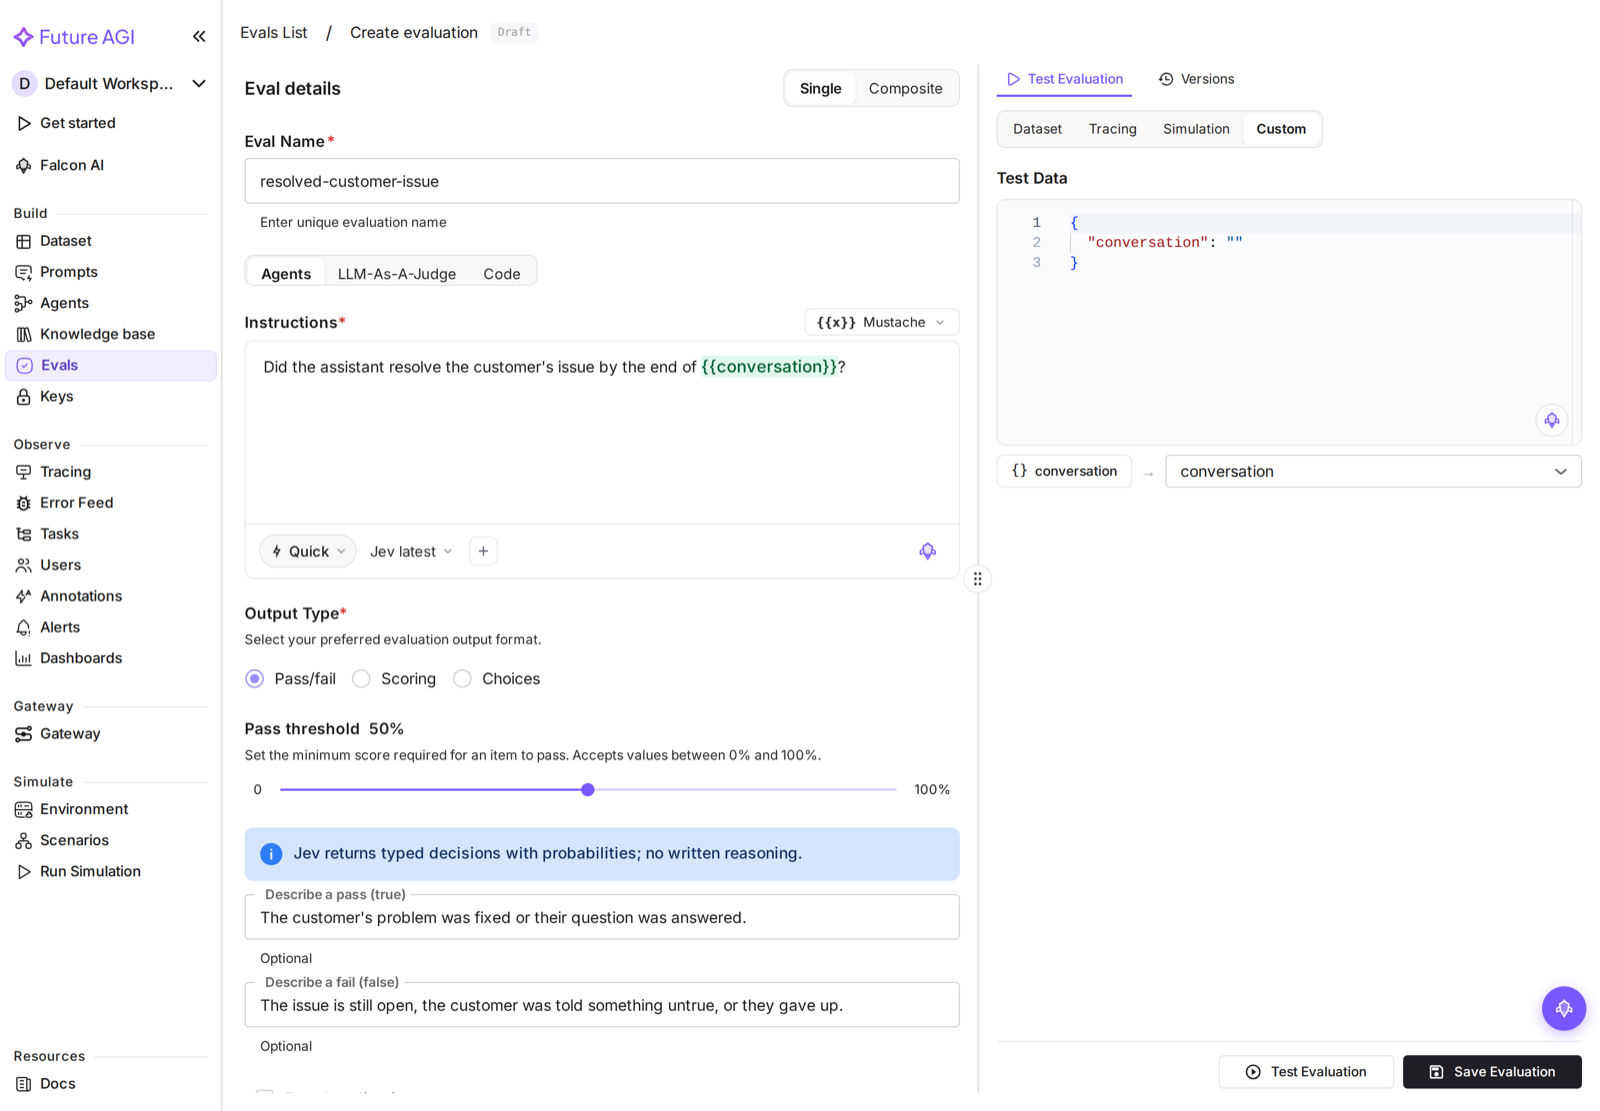
Output types
| Editor output | Jev result | Configuration and scoring |
|---|---|---|
| Pass/Fail | Probability that the pass condition is true | Optionally describe a pass and a fail. The pass threshold determines the verdict. |
| Choices | One label, its probability distribution and confidence | Define labels and their scores, with optional per-label descriptions. Jev selects one label; the label’s configured score is used. |
| Score | A score over an ordered rubric, with probabilities and confidence | Define 2–10 distinct ordered levels, from lowest to highest. The normalized score is the raw score divided by the number of intervals (level count − 1). |
Jev results show the decision and available probability or confidence data. There is no generated prose explanation. See Output types & scoring for the platform’s output and threshold concepts.
Controls that are unavailable for Jev
The editor disables multi-choice, few-shot datasets, tools, knowledge bases, internet checks, media inputs, automatic context injection, and agent modes other than Quick. These are not supported by Jev’s typed-decision adapter. Supply the relevant text through the evaluator’s mapped variables instead. The Score output uses ordered levels, not a choice-score configuration.
Switching models does not silently remove an existing incompatible setting. The editor preserves it and blocks testing or saving until you explicitly resolve it or choose a compatible model. If the template has extra messages, explicitly confirm Include extra messages as instructions before using them; chat roles are not preserved.
Gateway transport
Jev evaluations use the gateway’s /v1/systemone route by default, carrying the organization’s TypeSafe key for that call. The gateway must support the decision routes and have outbound access to TypeSafe. On self-hosted installs, upgrade the gateway before the backend when deploying this feature: an older gateway answers 404 and Jev evaluations fail.
Administrators can set JEV_TRANSPORT=direct to call TypeSafe from the API and workers instead. This changes the transport, not the key ownership or supported outputs. See Decision models and the configuration reference.
To ask a question from an Observe view without building an evaluator first, use Instant eval. Unlike Jev evaluators, Instant eval requires Enterprise access.
Other decision models
Jev is one of 35 decision models in the evaluator model picker. GPT-6 Luna Decisions, Perplexity Decider, Microsoft Decision 1, Solar Decide, Clef and the others work the same way: typed Pass/fail, Choices or Scoring answers with probabilities, on your own OpenAI, Perplexity, TypeSafe or OpenRouter key. See Use decision models as evaluators.
Bring your own LLM
You can also use your own model as the evaluator, from OpenAI, Bedrock, SageMaker, Vertex AI, Azure, or a custom endpoint. Reach for a custom model when you need a domain-tuned model, must keep inference in a region, or already pay for a model you want to reuse. See Use Custom Models.
Modality
An evaluator model can only score inputs it can read. Image evals run on any of the Turing models; audio evals need turing_large or protect. A text-only model cannot score an image or an audio input, so pick a multimodal one when the eval carries one.
Keep exploring
Questions & Discussion